YouTube Thumbnail Generator (Kontext Max)
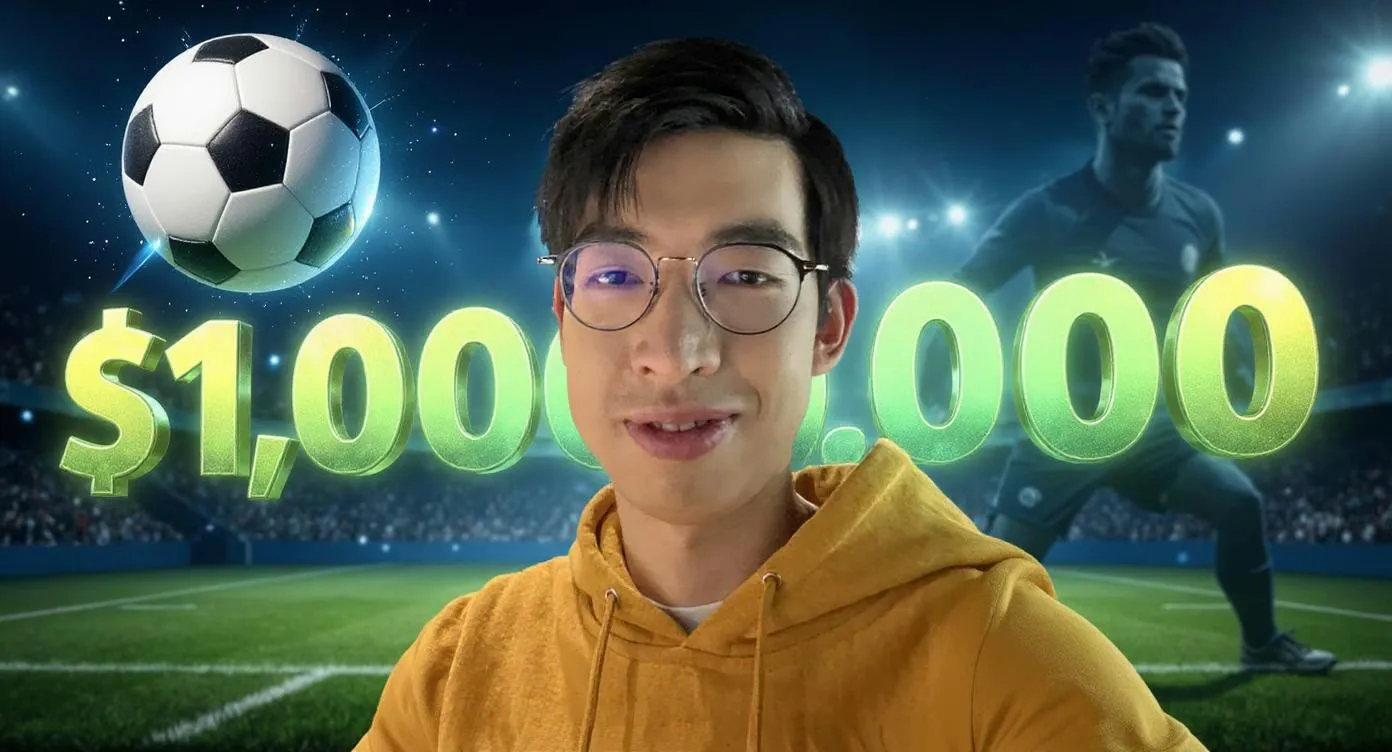
Upload a face photo and type your video title. An LLM writes the thumbnail prompt and Flux Kontext Max draws it with your face. For YouTubers and video editors.
- No GPU (runs on CPU)
- Image editing
- Text to image
- Free template
How it works
The graph has only 14 nodes and loads no local models.
You provide a face photo, a video title and an LLM name (default gpt-4.1-mini). The title is combined with fixed text by ComfyUIDeployStringCombine, and an LLMToolkitTextGenerator node using an OpenAIProviderNode turns it into a detailed thumbnail prompt. ShowText and Display_Text nodes let you read it.
That prompt and your face image go to FluxKontextMaxImageNode, which calls Flux Kontext Max to draw the thumbnail with your likeness. CheckImageEmpty and a SwitchAny node handle the case where no image is supplied, so the workflow can still pick a valid path. SaveImage stores the result.
The example title is a challenge-style headline in quotation marks, which shows how to mark text you want rendered in the image.
Tips
- Use a clear, front-facing photo with good lighting for the best likeness.
- Wrap text you want to appear on the thumbnail in quotation marks.
- Avoid copyrighted characters and sensitive content, since the template warns those may fail to generate.
- An OpenAI key in machine secrets is needed for the prompt step.
What you can use it for
- Thumbnails for YouTube videos
- A/B testing several thumbnail concepts per title
- Social cover images with a consistent face
- Batch thumbnails through an API
Run it in three steps
Open the template
Click Run on ComfyDeploy. The workflow, its custom nodes and models are set up for you on a cloud machine.
Add your inputs
Provide face photo and video title in the playground or the ComfyUI editor.
Run, share or deploy
Run it on a cloud machine, share it with your team as a playground, or deploy it as an API endpoint.
Frequently asked questions
What GPU does the thumbnail workflow need?
It runs on CPU. The image comes from the Flux Kontext Max node, which is an external API call, and the title prompt is written by an LLM, so no GPU is needed.
Can I put text on the thumbnail?
Yes. The input note says to put important text between quotation marks in the title, for example a number. It also warns that copyrighted or NSFW titles or images may fail.
How do I run the thumbnail workflow as an API?
Deploy it on ComfyDeploy and call the endpoint with a face image and a video title. The result is returned from the API response.